

Cyrillic OCR
Collection
Everything for Cyrillic OCR • 5 items • Updated • 1
Results on challenging OCR benchmarks featuring distortions, printing defects, and low-quality images.
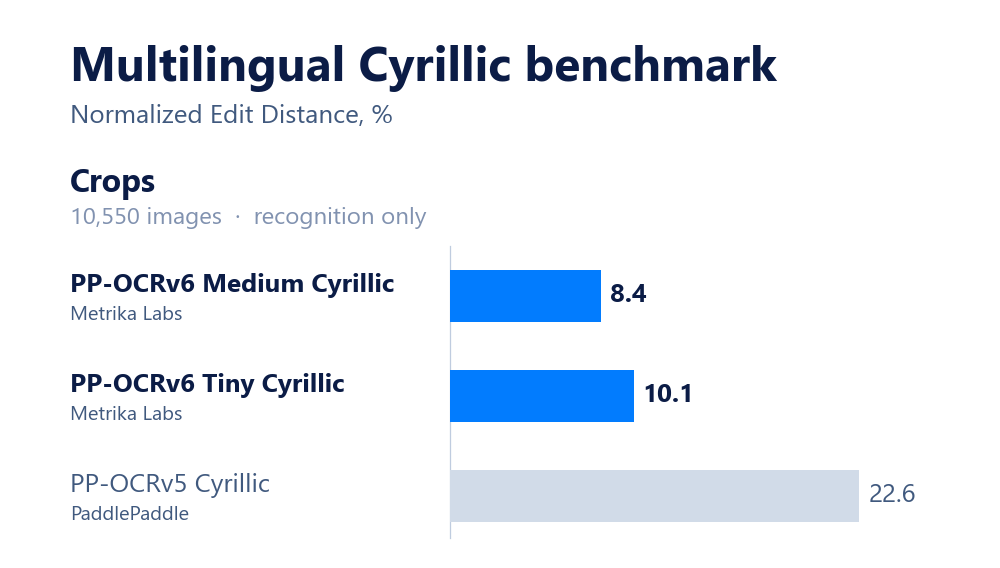
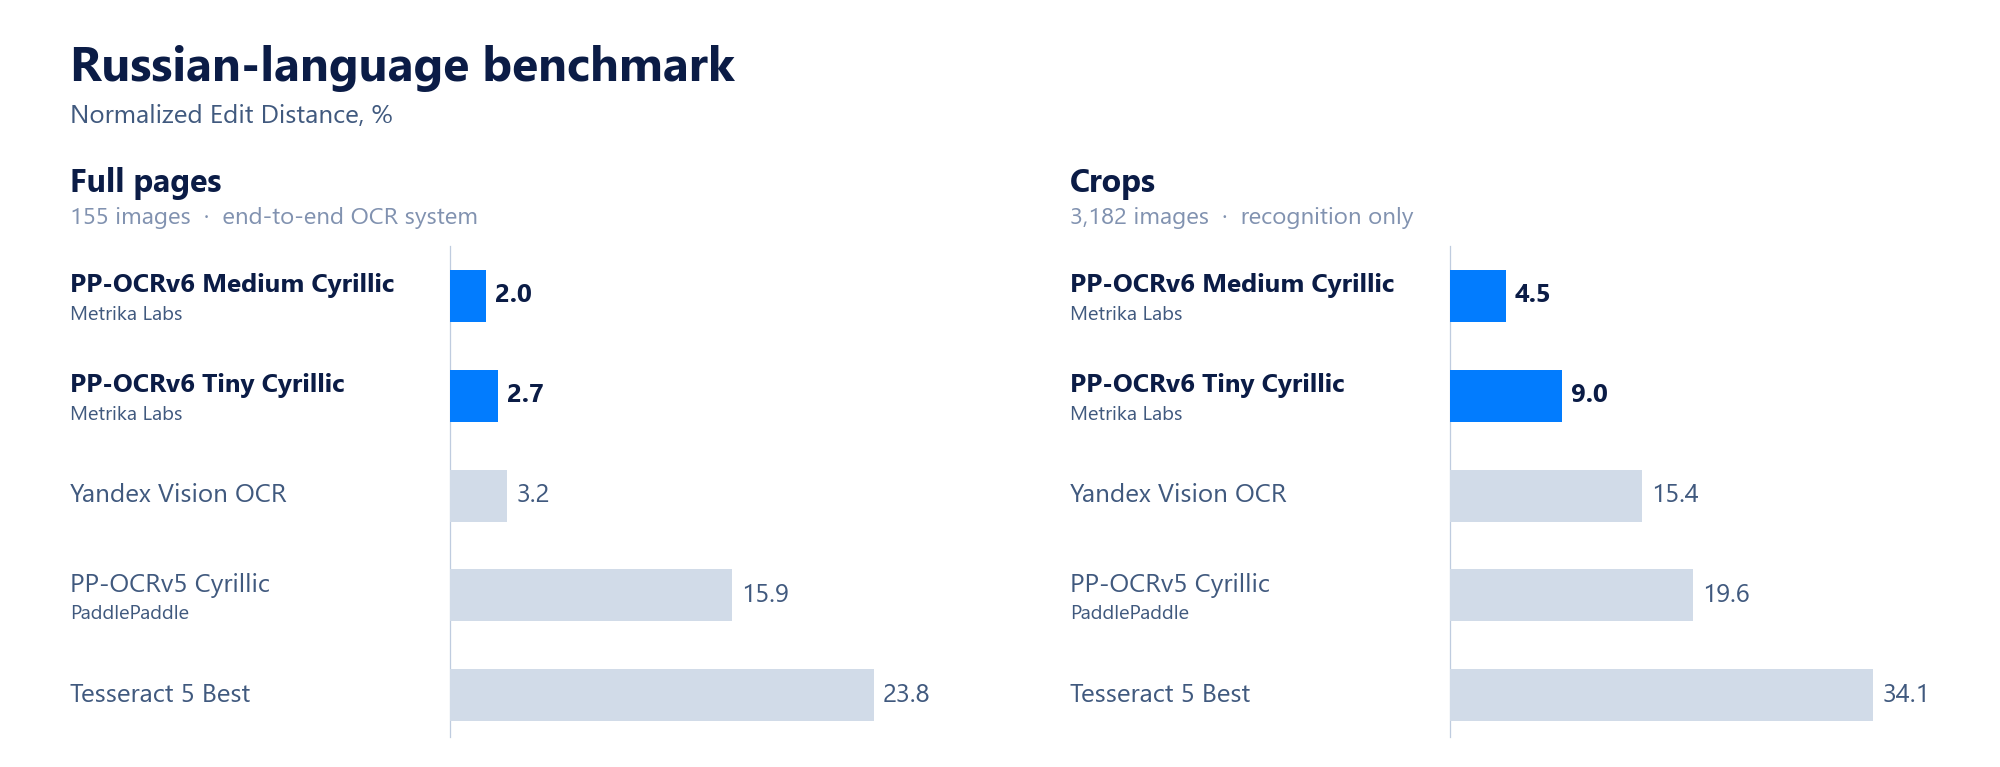
Russian-language OCR benchmark: ru-ocr-benchmark-hard
pip install paddleocr huggingface_hub
pip install paddlepaddle-gpu # For GPU inference
from huggingface_hub import snapshot_download
from paddleocr import PaddleOCR

# Download the model
model_dir = snapshot_download(repo_id="metrika-labs/PP-OCRv6_tiny_rec_cyrillic")

# Initialize OCR with standard PP-OCRv6 detection and Cyrillic recognition
ocr = PaddleOCR(
    text_recognition_model_name="PP-OCRv6_tiny_rec",
    text_recognition_model_dir=model_dir,
    text_detection_model_name="PP-OCRv6_small_det",
    use_doc_orientation_classify=False,
    use_doc_unwarping=False,
    use_textline_orientation=False
)

pipe = getattr(ocr.paddlex_pipeline, "_pipeline", ocr.paddlex_pipeline)
resize_op = pipe.text_rec_model.pre_tfs["ReisizeNorm"]
_orig_resize = resize_op.resize_norm_img
resize_op.resize_norm_img = lambda img, r: _orig_resize(
    img, min(max(r, 1.5 * img.shape[1] / img.shape[0]), resize_op.max_imgW / 48)
)

# Recognize the document
results = ocr.predict("document.jpg")
for res in results:
    for text, score in zip(res["rec_texts"], res["rec_scores"]):
        print(f"{text} ({score:.4f})")
PP-OCRv6 is a family of fast, lightweight text recognition models from PaddlePaddle. The models were trained by Metrika Labs on 7.5 million varied examples of printed and handwritten text from real document scans and synthetic images.
80% of the examples are in Russian. The other 20% are in Kazakh, Belarusian, Uzbek, Tajik, Ukrainian, Bulgarian, Serbian, Macedonian, Tatar, Kyrgyz, Mongolian, Bashkir, Ossetian, Chuvash, Chechen, Yakut, Avar, and other languages that use Cyrillic.
The models work with PaddleOCR and are also available in ONNX format for fast CPU inference with RapidOCR.
The current version supports handwritten text only in Russian. It reads clear handwriting well, but may make mistakes with cursive or less legible handwriting.
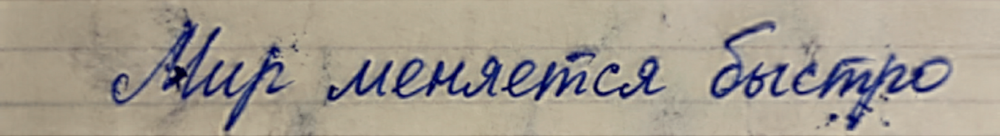
PP-OCRv6 Medium: Мир меняется быстро (score: 0.9882)
PP-OCRv6 Tiny: Пир меняется быстро (score: 0.8412)
Benchmark for evaluating OCR model quality on Russian text: metrika-labs/ru-ocr-benchmark-hard
Some handwriting examples come from AntiplagiatCompany/HWR200
Original PaddleOCR repository: PaddlePaddle/PaddleOCR
RapidOCR repository: RapidAI/RapidOCR
Base model
PaddlePaddle/PP-OCRv6_tiny_rec